We have more data than ever to help us understand the world around us. The hard part is figuring out what data is valuable and what it means to help our understanding. In other words, context.
This has always been the case in the world of analytics. Agents that use data have the same issue but with higher stakes. An analyst who gets bad data makes one bad call and hopefully realizes their mistake. An agent that misunderstands your business makes the same mistake thousands of times, confidently, and acts on it. That’s why an enterprise AI strategy is really a data strategy. Most of the context an agent needs lives in the data a company already uses to run itself, wrapped in meaning that was never written down.
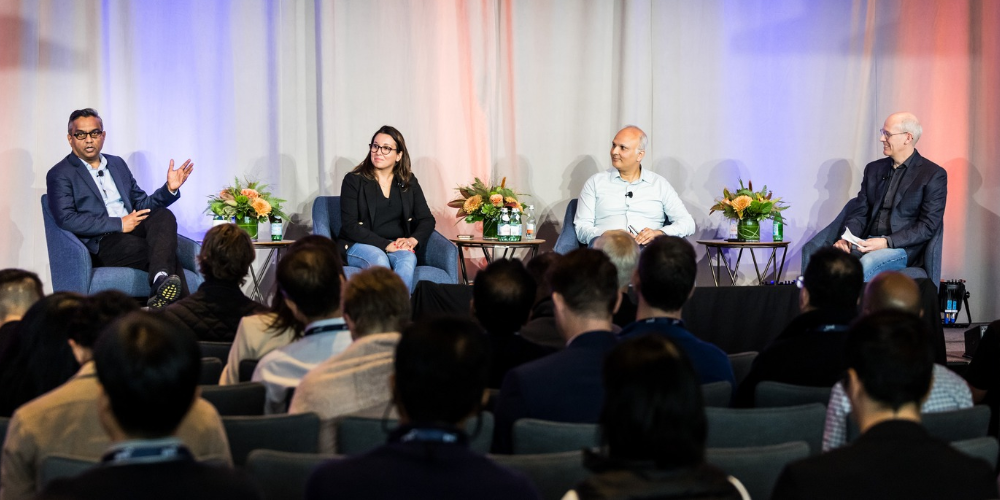
How can we make the data an enterprise has into a form that is understandable and useful for AI to help in the way we all imagine it can? I spent time discussing exactly this question at our IA40 Summit in September with three people who run some of the largest data platforms in the world: Rahul Auradkar, previously of Salesforce Data 360, Zaheera Valani of Databricks, and Ganapathy “G2” Krishnamoorthy of AWS Database Services.
The most effective agents will be the ones that understand a company’s data: which parts are important to answer a given question, what they mean in the context of the business, and how that meaning changes as the business changes. For builders, capturing a customer’s semantics is becoming part of the product, and for the best teams, part of the moat.
Cost per Correct Answer Is the Metric to Watch
When an enterprise agent gets something wrong, the usual cause is missing business context to give it understanding. As one panelist put it, the models are “incredibly intelligent, but they’re corporate stupid.” A model can reason about almost anything and still not know how your company defines a customer, a booking, or revenue. Giving agents that context makes a measurable difference. Zaheera of Databricks said she sees roughly 80% accuracy when a model works through a context layer, compared to 50% without.
The first instinct is to give the model everything: every piece of data, every document, every conversation transcript. That fails twice, however: once on cost and again on accuracy. The right answer gets buried in an avalanche of information. Salesforce learned this firsthand. Its customers first wanted their own data fed into models so the answers reflected real facts about their business. Once that worked, they started noticing the bill. The challenge became: “What’s the minimal context needed for the best outcome with optimized costs?”
The answer looks a lot like traditional data modeling and governance: clean up the data and connect what matters before the model sees it. Salesforce resolves its own roughly 320 million customer profiles down closer to 145 million real people, then uses graphs to connect the records and documents that actually matter for a given question. The model processes far less, which keeps costs down, and works from a cleaner picture, which keeps accuracy up. The discussion pointed to that combination as a reason these approaches are going mainstream: they make intelligence more cost efficient while driving real business value.
Cost per correct answer comes straight out of your gross margin. Measure it per customer and per task, using that customer’s real questions instead of generic benchmarks. Do the expensive work once, up front: resolve duplicate records, build a relationship graph, and precompute what’s reusable, so each request pulls only what it needs. Business buyers will ask how you keep that cost down, so have an answer ready.
Meaning Has to Expand Beyond the Application
The root of the problem is that business meaning was never stored with the data. It lives in application logic and human processes that operate on that data. “This was a challenge if you go back to self-service BI in Tableau days,” G2 said, “and that problem still remains with AI.” At Meta, he saw “video viewed” mean three different things depending on which app produced the record: the sound was on, it played for 30 seconds, or the viewer reached the end. A person on the right team would know which was which, but an agent reading the table has no chance.
Analytics tried to fix this with semantic layers like LookML and dbt, which defined each metric once so every dashboard agreed. Agents need that discipline across every system they touch, including the seams where a record of a purchase lives in one system and marketing in another. There are different approaches to solving this hard problem. AWS enables teams to place a markdown file describing the data model next to the database. The goal is a semantic model that travels with the data and stays current.
That changes what deployment looks like. The tables you connect to won’t tell your agent what the business means, so plan to uncover those meanings at every customer, starting with what already exists: dbt models, markup layers like LookML, dashboard definitions, and application code. It’s also an opportunity. Whoever makes a company’s business meaning portable and current will own a layer every other agent depends on. And if you build an application, surface what your data means alongside the data, because agents will increasingly use your product without using its human interfaces.
Definitions Decay, So Context Has to Learn
Hand-built semantic models start going stale the day they ship. Products get renamed, metrics get redefined, and teams invent new terms faster than anyone updates the documentation. Databricks pairs explicitly modeled context with context that’s generated automatically from how the data is used, and its Genie Ontology product flags when an explicit definition has drifted so someone can fix it.
Context also depends on who’s asking. A booking means one thing in finance and another in sales. That’s manageable inside one domain. It gets hard at enterprise scale. General Motors runs roughly 1,000 agents in production, and every new employee, customer, or agent needs context that crosses those domains and knows which source is authoritative for which question. Time matters too. The best agents combine what they learn within a session with a customer’s long-term history, and weigh recent behavior more heavily. For instance, a shopping agent usually cares much more about last week than six months ago.
Treat the semantic layer as something you keep running long after setup. Build the loop in: capture the questions your agent gets wrong and the corrections people make, and use them to flag definitions that have drifted. Make context depend on who’s asking and which source is authoritative for them, since your agent will be one of many inside a large customer. Tune memory to the job, because recency should dominate for a shopping agent while a compliance agent may need the full history. Each correction makes the context more specific to that customer, which raises the cost of switching to a competitor.
Looking Forward
Context is becoming a first-class component of the data stack. In the analytics era, the semantic layer sat on top of the data to keep metrics consistent across reports. Agents need it everywhere they act: in the database, in the applications that write the data, and in the memory each agent carries from one task to the next.
Context and accurate understanding are where the durable value is. Storage and compute will keep getting cheaper. The understanding of a business in context of the world around it, captured, kept current, and readable by any agent, is much harder to replicate. The products that win will be the ones that get the context right before they act.
You can find all our 2026 IA40 session recordings here.